Generate It, Annotate It, Ship It: Building CCTV-Ready Training Data Without Touching a Labeling Tool
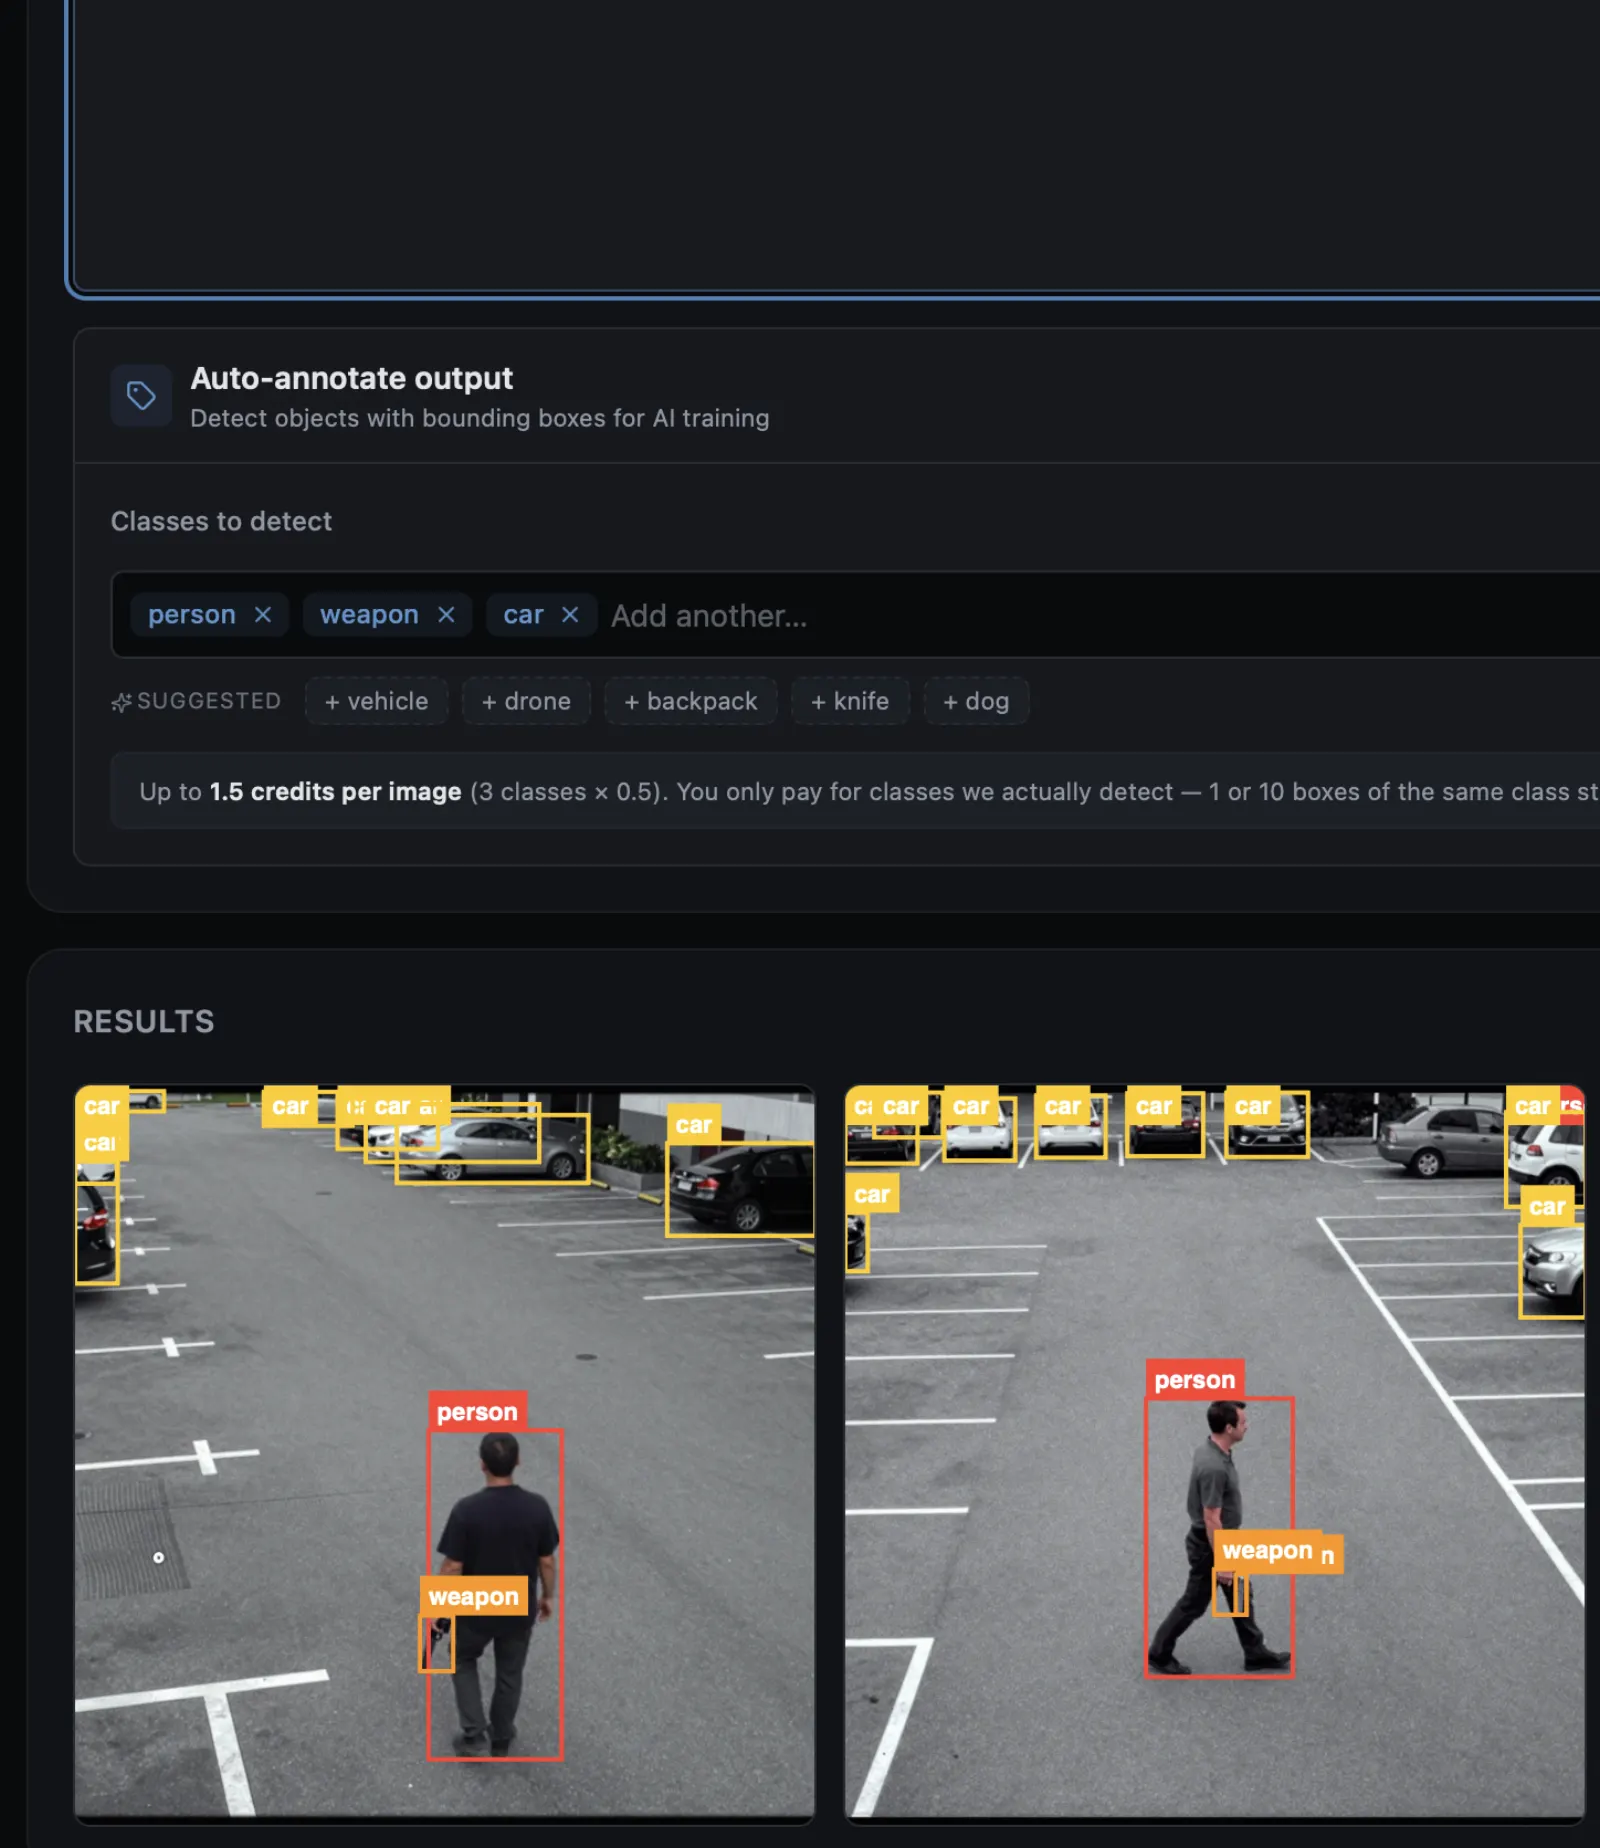
Two synthetic CCTV frames, three classes (person, weapon, car), zero manual labeling. Generated and annotated in Simuletic Studio in about thirty seconds.
Update, October 2026: the self-serve Simuletic Studio described below has been retired, and the credit pricing in this post no longer applies. The same generate-and-label pipeline now produces our dataset library and the custom datasets we build on your camera angles; an API is coming.
Labeling is the part of the computer vision job nobody puts on a slide. Generating the model is fun. Training is fun. Deploying is, on a good day, fun. Sitting in a labeling tool at 11pm dragging boxes around the same parking-lot frame for the fourteenth time is not fun, and it's where most CV projects quietly lose two months.
We just shipped the feature that removes that step entirely. You write a prompt — say, "a person walking through a public space carrying a small handheld pistol down by their side, full-body shot, CCTV camera" — Simuletic Studio renders the image, and a second later it hands you back YOLO-format bounding boxes for whatever classes you asked for. No labeling tool. No second vendor. No third invoice.
The screenshot at the top of this post is the actual output of that workflow — two frames, three classes, ready to drop into an Ultralytics training run.
The Two-Step Workflow That Used to Take Weeks
Here's what the Studio looks like with auto-annotation switched on. You pick a camera view (standard, CCTV, aerial / drone), write your scene, choose resolution, batch size, and the classes you want detected. Confidence threshold sits at 0.40 by default — high enough to filter the obvious junk, low enough not to miss small or partially occluded objects.
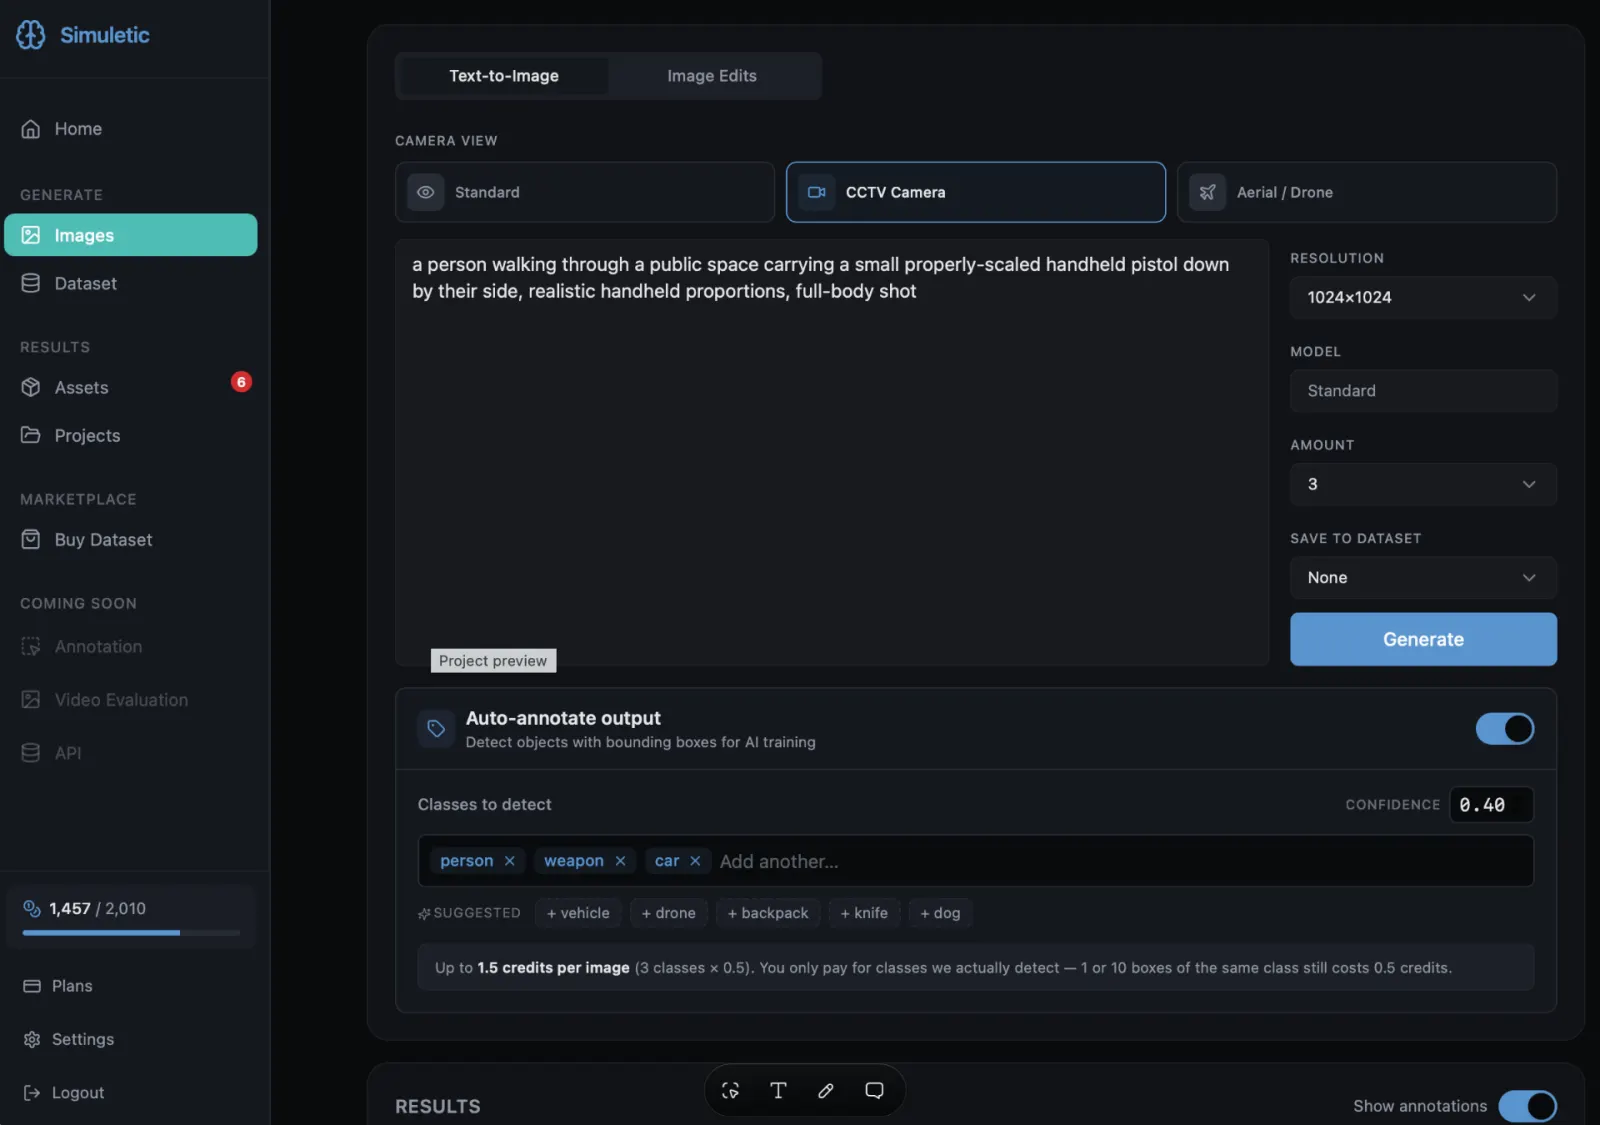
The Studio with auto-annotation enabled. Add up to eight classes per generation; we'll detect every instance up to ten boxes per class.
Hit generate. That's it. Each image gets a .txt file in standard YOLO format next to it (class id, normalized cx, cy, w, h) and the classes are saved as a data.yaml for you. The bounding boxes are toggled on and off with a single switch on the results page so you can sanity-check before exporting.
The synthetic-vs-real argument is over for most CV teams. The argument that's still alive is annotation cost. Auto-annotation kills it: the labels come out of the same render pipeline that drew the scene.
What's Actually Happening Under the Hood
We run a SAM3-based open-vocabulary detector over every generated frame, one class at a time so class identity is never lost in a mask batch. For each class we get back pixel-space x, y, width, height for every instance, then normalize, aggregate, and write a standard YOLO label file.
Two small things are worth knowing:
- Per-class detection cap of 10. Enough to cover a crowded parking lot or a dozen pedestrians without ever returning a wall of noise from a low-confidence model that thinks every shadow is a person.
- Tunable confidence (0.05 → 0.90). Default 0.40 is the sweet spot for medium-distance CCTV. Drop to 0.20 if you're shooting aerial / small-object scenes. Push to 0.60 if you want only the cleanest training signal.
CCTV Use Cases Customers Are Shipping In a Day
The first wave of teams using this are all building CCTV-adjacent systems. A few patterns we keep seeing:
Parking lots and smart cities
Classes: person, vehicle, backpack. The header image of this post is exactly that — synthetic frames a smart-city vendor would use to train license-plate-area and pedestrian-flow models without filming real people.
Retail loss prevention
Classes: person, weapon, backpack. Pair with our CCTV shoplifting dataset for pose + behavior signals, and use auto-annotation to extend it with your own store layouts.
Perimeter and ATM security
Classes: person, weapon, knife. The ATM robbery dataset explains why role-aware annotations matter here — auto-annotation gives you the boxes, the scene is what teaches the model intent.
Fire and smoke watchtowers
Classes: smoke, fire. See our smoke & fire detection dataset on why the first sixty seconds matter — auto-annotation makes adding your local tower angles trivial.
Aerial & drone surveillance
Classes: drone, vehicle, person. The Studio's aerial camera view + auto-annotation pairs naturally with our existing airport drone dataset.
"But Are the Boxes Any Good?"
Reasonable question. Look at the parking-lot frames at the top of this post: every car in both lots is boxed cleanly, including the partially-occluded vehicles in the back row. Both walking pedestrians are tight, full-body boxes. The handheld pistol — a 30-pixel-wide object inside a 1024-pixel image — is also caught in both frames.
The honest answer is: SAM3 is excellent at common, recognizable objects (people, vehicles, animals, large props), very good at moderately specific terms (weapons, drones, backpacks, knives), and where it needs help is on small objects in busy scenes — that's where dropping the confidence to 0.25–0.30 pulls them back in. The threshold is right there in the panel, no API call needed.
For teams who need pixel-perfect labels on niche classes, this is still most of the way there: it gives you a high-quality first pass that a junior reviewer can clean up in minutes per image instead of hours.
Export Straight to YOLO
Hit export on any dataset and you get a single zip: images/, labels/ with one .txt per image, and a data.yaml with your class names. Drop it straight into Ultralytics, Roboflow, or your own training pipeline. No conversion script. No "wait, what format is this in" Slack thread on a Friday afternoon.
Get Labelled Data Today
The Studio is retired, but the pipeline is not: every dataset in our library and every custom dataset we deliver comes out of it with boxes already drawn and checked. Start with a ready-made dataset (free sample, then a research or commercial licence), or send us your camera views and classes for a custom pack.
The best labeling tool is the one you never have to open. Generate the scene, get the boxes, train the model. That's the whole loop now.
Related reading: Shoplifting detection dataset, Smoke & fire detection, and Weapon detection.
Related Articles
How We Document Our AI Systems and Stay Ready for the EU AI Act
A practical guide to classifying and documenting AI systems under the EU AI Act.
Read MoreSynthetic Weather Variations: Complete Your Dataset with Any Condition
Generate nighttime, rainy, foggy, and stormy variations of your training data in seconds.
Read MoreWhy Synthetic Video Is the Future of Computer Vision
How synthetic video solves the data dilemma in computer vision.
Read More