Platform · generation on request
The pipeline behind every Simuletic dataset.

01How it works
From a scene spec to a checked, labelled dataset.
- 01
Scene and camera
Every run starts from a spec: the environment, camera height and angle, lens, lighting and weather. Or from photos of your own empty camera views.
- 02
Generate
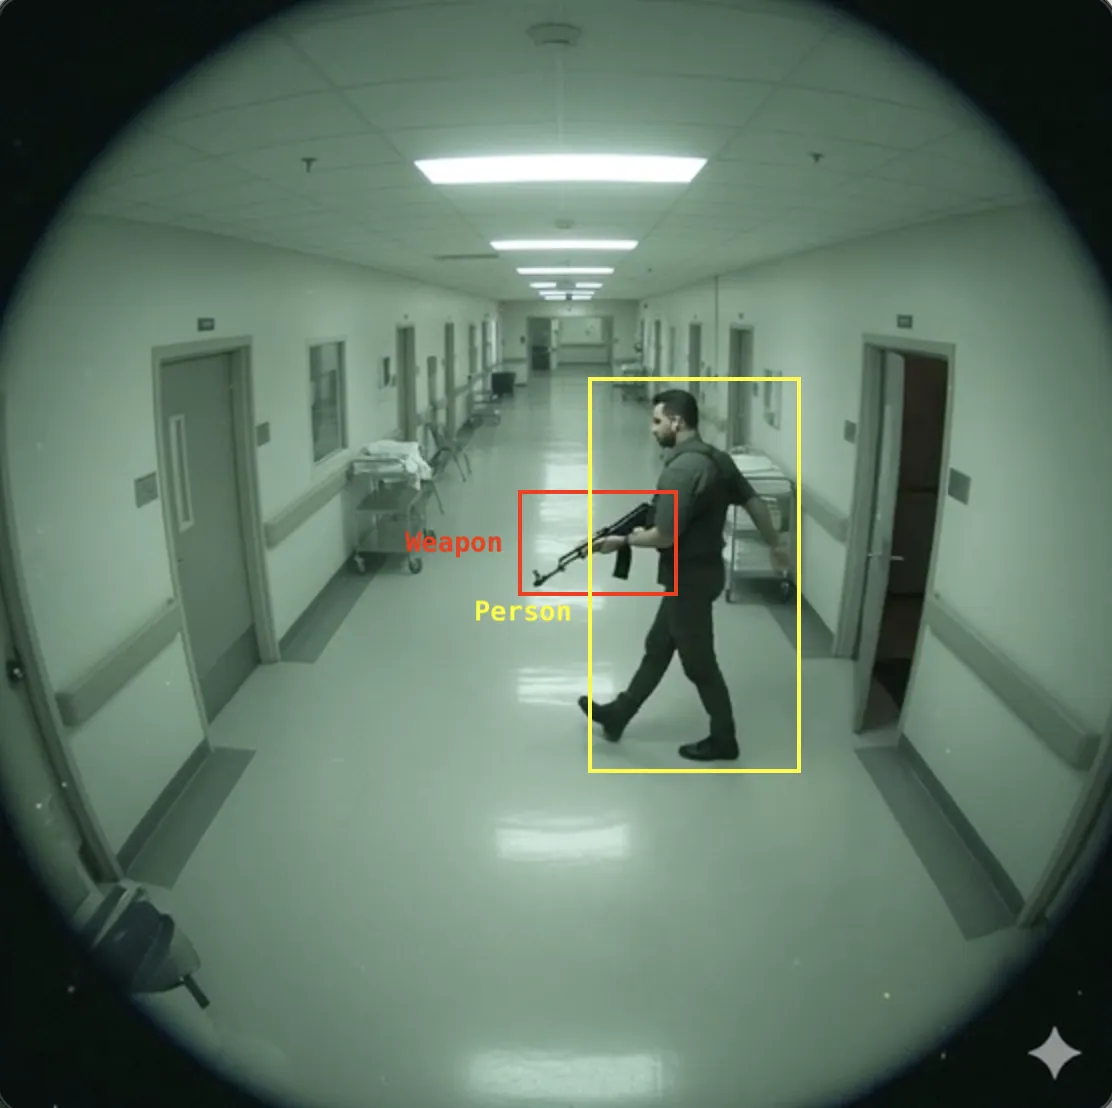
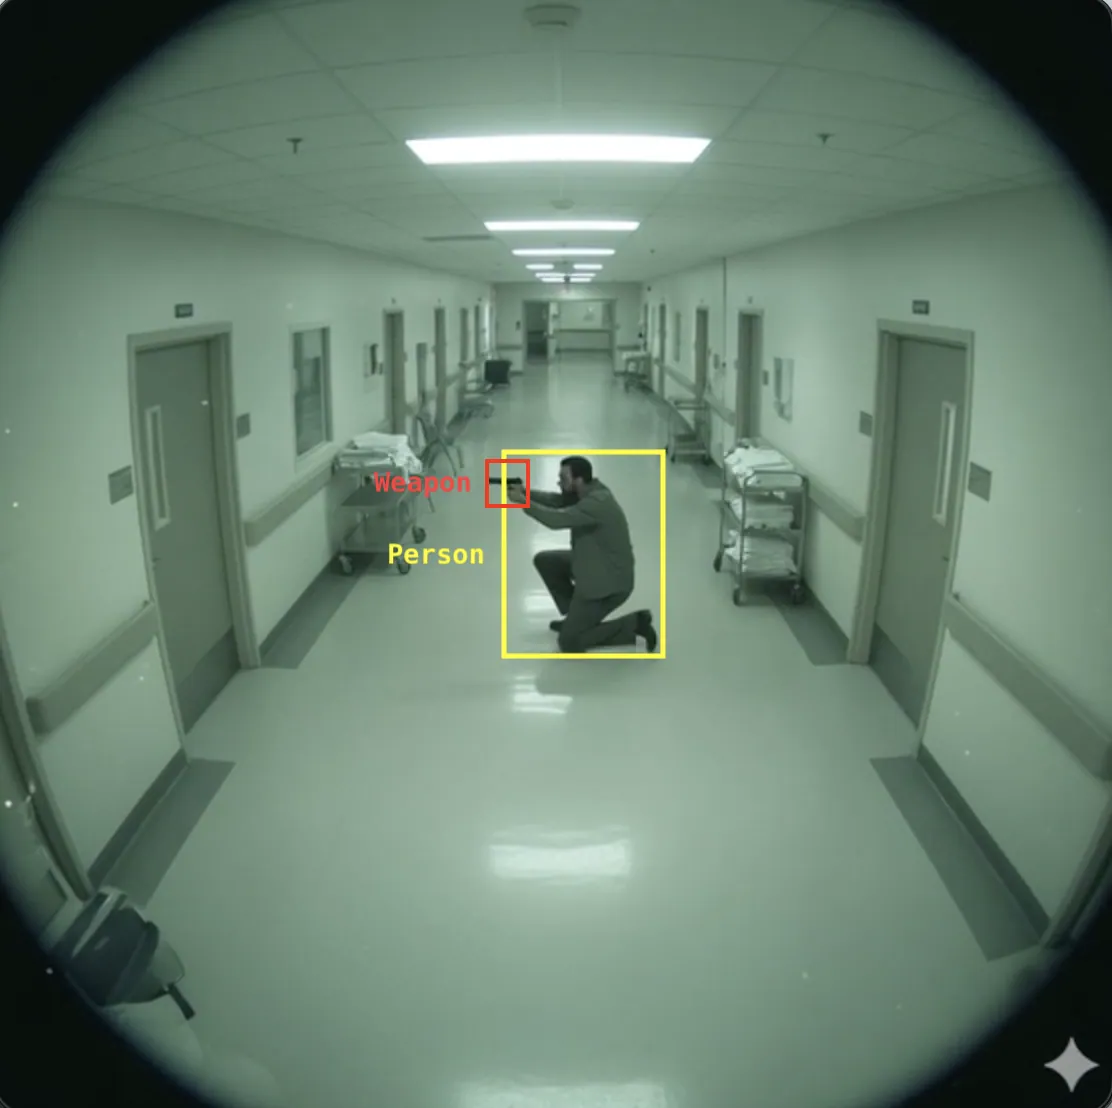
Open-weight generative models render the event into the scene: a handgun at a ticket gate, a fall in a corridor, smoke at a loading dock. Look-alikes such as umbrellas, phones and drills are rendered too, so the model learns what not to flag.
- 03
Label
Detection and segmentation models box every person and target object. Masks, pose keypoints and attributes are added when the project needs them.
- 04
Check
A vision-language model reviews every image: is the object really there, does the frame read as CCTV, is each box on the right object. Failures are rejected or re-labelled, and a sample is reviewed by a person.
- 05
Deliver
Images or video clips with YOLO and COCO labels, a fixed train / val split and a dataset card with class counts and how the set was checked.
Only images that pass every check are delivered. The generation recipes stay on our side; you receive the data, the labels and the dataset card.
02Labels
Fully labelled, not just generated.
Bounding boxes
Every person and target object in the frame, including small and distant ones. Nothing is left for you to annotate.
Hard negatives
Look-alike objects in the same scenes, labelled as background, to bring false alarms down.
Masks, pose and attributes
Segmentation masks, body keypoints, clothing and carried objects, on request.
VLM captions
Grounded captions and question-answer pairs for vision-language models.
Video labels
Per-frame boxes, tracking IDs and event start and end times for clips.
Dataset card
Class counts, scene and lighting mix, and how the set was checked.
More on captions and reasoning data on the VLM training data page, and on video in synthetic CCTV video datasets.
03Access
What you can use today.
Available now
Generation on request
Tell us the scenes, classes and volume. We run the platform and deliver a labelled, checked set. Priced per project.
Send a requestAvailable now
Datasets and custom packs
Ready-made datasets from the library, or a fixed-price pack built on photos of your own camera views.
Early access
API & MCP
Order labelled images from your training code, or let an AI agent order them over MCP. It opens as a private beta first.
Join early accessQuestions
Platform questions
Can I use the platform myself?
Not yet. There's no general access while we finish the self-serve side. Today we run the platform for you: send a request and we deliver the labelled data. An API and MCP server will open first as a private beta.
How is a generation request different from a custom dataset?
Both run on the same platform. A custom dataset is a fixed-price pack built on photos of your own cameras. A generation request can be anything the platform makes: more images of one class, new look-alike negatives, a scene type we don't have yet, or a short video test.
Are the images fully labelled?
Yes. Every person and target object is boxed, and every image is checked before delivery. Labels come in YOLO and COCO; masks, keypoints, attributes and VLM captions are available on request.
Is any real footage used?
No real incident footage is used. The people and events are generated. For custom work we use photos of your empty scenes, which you provide.
What does a generation run cost?
It's priced per project, by volume, label types and whether it's images or video. Tell us what you need and we reply within one working day with a timeline and a price.
Request