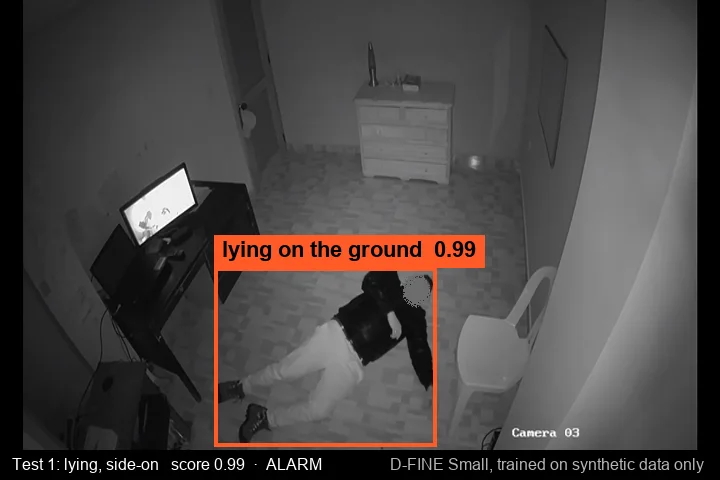
 Research preview
Fall Detection Model
Detects a person lying on the ground or floor in a CCTV frame, and stays quiet for sitting, kneeling, standing and walking.
- Real-footage result
- 97.4% at 5% FA
- Sizes
- Small 10.2 M · Nano 3.7 M
Model library
Research previewDetects a person lying on the ground or floor in a CCTV frame, and stays quiet for sitting, kneeling, standing and walking.
Simuletic CCTV state models are small detectors for one state worth an alarm each, trained only on the matching Simuletic dataset and released under Apache-2.0 once they pass their real-footage bar.
Open a card for the full results, the sizes and the caveats. The training data is the same dataset you can license from the dataset library, so you can train your own model on it or add it to your real footage.
How we measure
Public real-footage sets with usable licences, never trained on. For the fall detection model: CAUCAFall subjects 6–10 (CC BY 4.0) and GMDCSA-24 (MIT), a second home the model never saw.
We score the state the data teaches: is the person lying on the ground or floor. The second either side of a fall onset is excluded, and lying in bed or on a sofa is out of scope.
Share caught when 5% or 1% of normal frames may alarm; falls caught at a 5% and 10% clip false-alarm rate; mean and range over seeds, never the best seed.
Full method, table and misses: the case study
FAQ
A person lying on the ground or floor in a CCTV frame: the state behind fall, collapse and assault alarms. It stays quiet for sitting, kneeling, crouching, standing and walking. The falling motion itself is not scored, and lying in bed or on a sofa is out of scope.
Real footage only. Every number on these pages comes from public real-footage test sets the model never trained on (CAUCAFall, CC BY 4.0, and GMDCSA-24, MIT). Synthetic validation scores are never reported as results.
Only our synthetic CCTV Fall & Incident Detection Dataset: 1,000 images with 178 confusers such as sitting and kneeling. You can license the same dataset to train your own model, or add it to your real footage.
Early access is on request now. Apache-2.0 weights for both sizes are released on Hugging Face after round 2 passes its bar (targeted top-up data and public-space tests).
On our data, D-FINE transferred to real footage far better than YOLO26 with its default recipe (frame AP 0.985 vs 0.449 for the synthetic-only models on the first real test). D-FINE is also Apache-2.0, so customers can ship it commercially; Ultralytics YOLO is AGPL-3.0, so we measure it as a reference and never distribute it.
We train on your camera views with our data, score on your footage under a scoring-only agreement, and report the same metrics as here.