15 Video Datasets for Computer Vision, Compared (2026)
One table: size, labels, footage and licence for the video datasets computer-vision teams actually use, and what none of them covers.
In short: for pre-training a video backbone, use Kinetics or Something-Something. For activities in context, AVA and Charades. For skeletons, NTU RGB+D. For surveillance, MEVA is the only large CCTV-style set with a commercial-friendly licence (CC BY 4.0); UCF-Crime, XD-Violence and RWF-2000 have the incidents but restrictive or unclear terms. None has many examples of falls, weapons or theft from your own camera angle.
This page is the comparison. For how to label activity data and build a HAR dataset, read the human activity recognition guide; for incident detection on CCTV, the video anomaly detection guide.
The comparison table
Sizes are as published; YouTube-based sets lose clips over time as videos are removed. "Check the project page" means we could not find a licence statement to verify: treat it as not cleared for commercial use until you have.
| Dataset | Size | Labels | Footage | Licence |
|---|---|---|---|---|
| Action recognition | ||||
| UCF101 (2012) | 13,320 clips | 101 action classes, one per clip | YouTube, mostly handheld | None stated; clips are third-party YouTube videos |
| HMDB51 (2011) | ~6,800 clips (papers report 6,766–6,849) | 51 action classes | Films and web video | Check the project page |
| Kinetics-400 (2017) | ~306K clips of ~10 s at release; fewer still online | 400 action classes | YouTube, mostly handheld | None in the official readme; third-party YouTube content |
| Kinetics-700 (2019) | ~650K clips of ~10 s | 700 action classes, ≥600 clips each | YouTube, mostly handheld | None in the official readme; third-party YouTube content |
| Something-Something v2 | 220,847 clips | 174 hand–object interaction classes | Crowd-workers filming themselves | Qualcomm licence; check its terms |
| Activities in context | ||||
| AVA Actions (2018) | 430 movie clips of 15 min | 80 atomic actions, boxed per person (spatio-temporal) | Feature films | Annotations CC BY 4.0 (Google); the films are copyrighted |
| Charades (2016) | 9,848 videos | 157 action classes, 66,500 temporal annotations | Crowd-workers acting at home | Check the licence file in the download |
| Skeleton / multi-modal | ||||
| NTU RGB+D 60 / 120 (2016 / 2019) | 56,880 / 114,480 samples | 60 / 120 classes incl. falling and mutual actions | Lab, three Kinect v2 sensors: RGB, depth, IR, 3D skeletons | Academic research only; commercial use needs permission |
| Surveillance & anomaly | ||||
| MEVA (2020) | 9,300+ h recorded; ~22 h of annotations public | 37 activity types | 38 RGB and thermal IR cameras at one venue, plus UAV | CC BY 4.0 |
| UCF-Crime (2018) | 1,900 untrimmed videos, ~128 h | 13 anomaly classes + normal; video-level training labels | Real CCTV from YouTube and LiveLeak | Research use only |
| XD-Violence (2020) | 4,754 videos, 217 h, with audio | 6 violence classes + normal | Movies and YouTube: CCTV, handheld, dashcam | Check the project page |
| RWF-2000 (2019) | 2,000 clips of up to 5 s | Violent / non-violent | Surveillance footage from YouTube | Commercial use and redistribution need the lab's approval |
| ShanghaiTech Campus | 437 videos, 130 abnormal events | One-class (normal vs. abnormal), pixel masks | Fixed campus cameras, 13 scenes | Check the project page |
| CUHK Avenue (2013) | 37 clips, 47 abnormal events | One-class, boxed abnormal events | One fixed camera on a walkway | Check the project page |
| UBnormal (2022) | 543 videos, 29 scenes | Open-set anomalies, pixel masks | Synthetic people on real background photos | CC BY-NC-ND 4.0 |
Papers: Soomro et al. UCF101; Kay et al. Kinetics; Carreira et al. Kinetics-700; Gu et al. AVA; Sigurdsson et al. Charades; Liu et al. NTU RGB+D 120; Corona et al. MEVA; Sultani et al. UCF-Crime; Wu et al. XD-Violence; Cheng et al. RWF-2000; Acsintoae et al. UBnormal.
How to pick
- Pre-training a video model: Kinetics-400/700 for appearance, Something-Something v2 when motion direction matters (pushing vs. pulling).
- Who is doing what, where: AVA (boxes per person per second) and Charades (several overlapping activities per video).
- Skeleton-based recognition: NTU RGB+D 60/120, the standard for graph-convolution models; research-only.
- Surveillance: MEVA for licence-clean CCTV-style activity; UCF-Crime and XD-Violence to compare against published anomaly results; ShanghaiTech and Avenue for one-class methods.
- Shipping a product: read the licence column first. Most of this table is research-only or unclear.
What none of them covers
The public sets were built to compare models, not to ship safety products. Three gaps show up in every CCTV project we see:
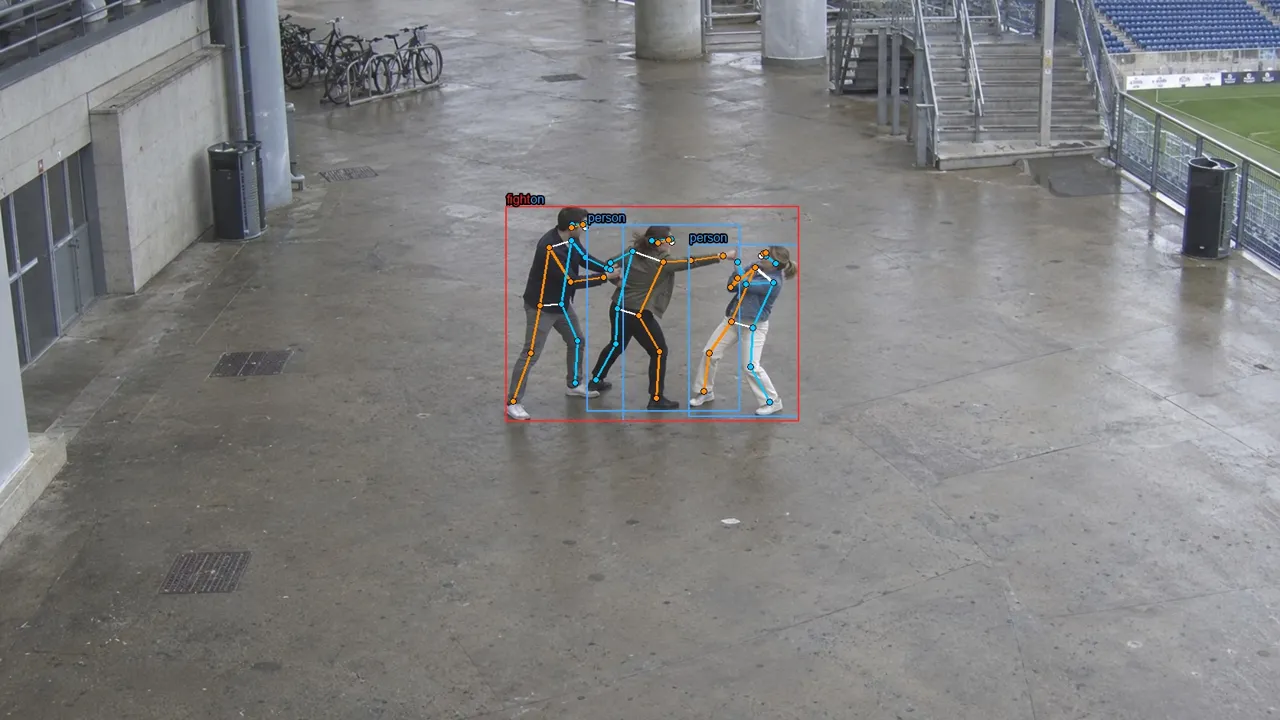
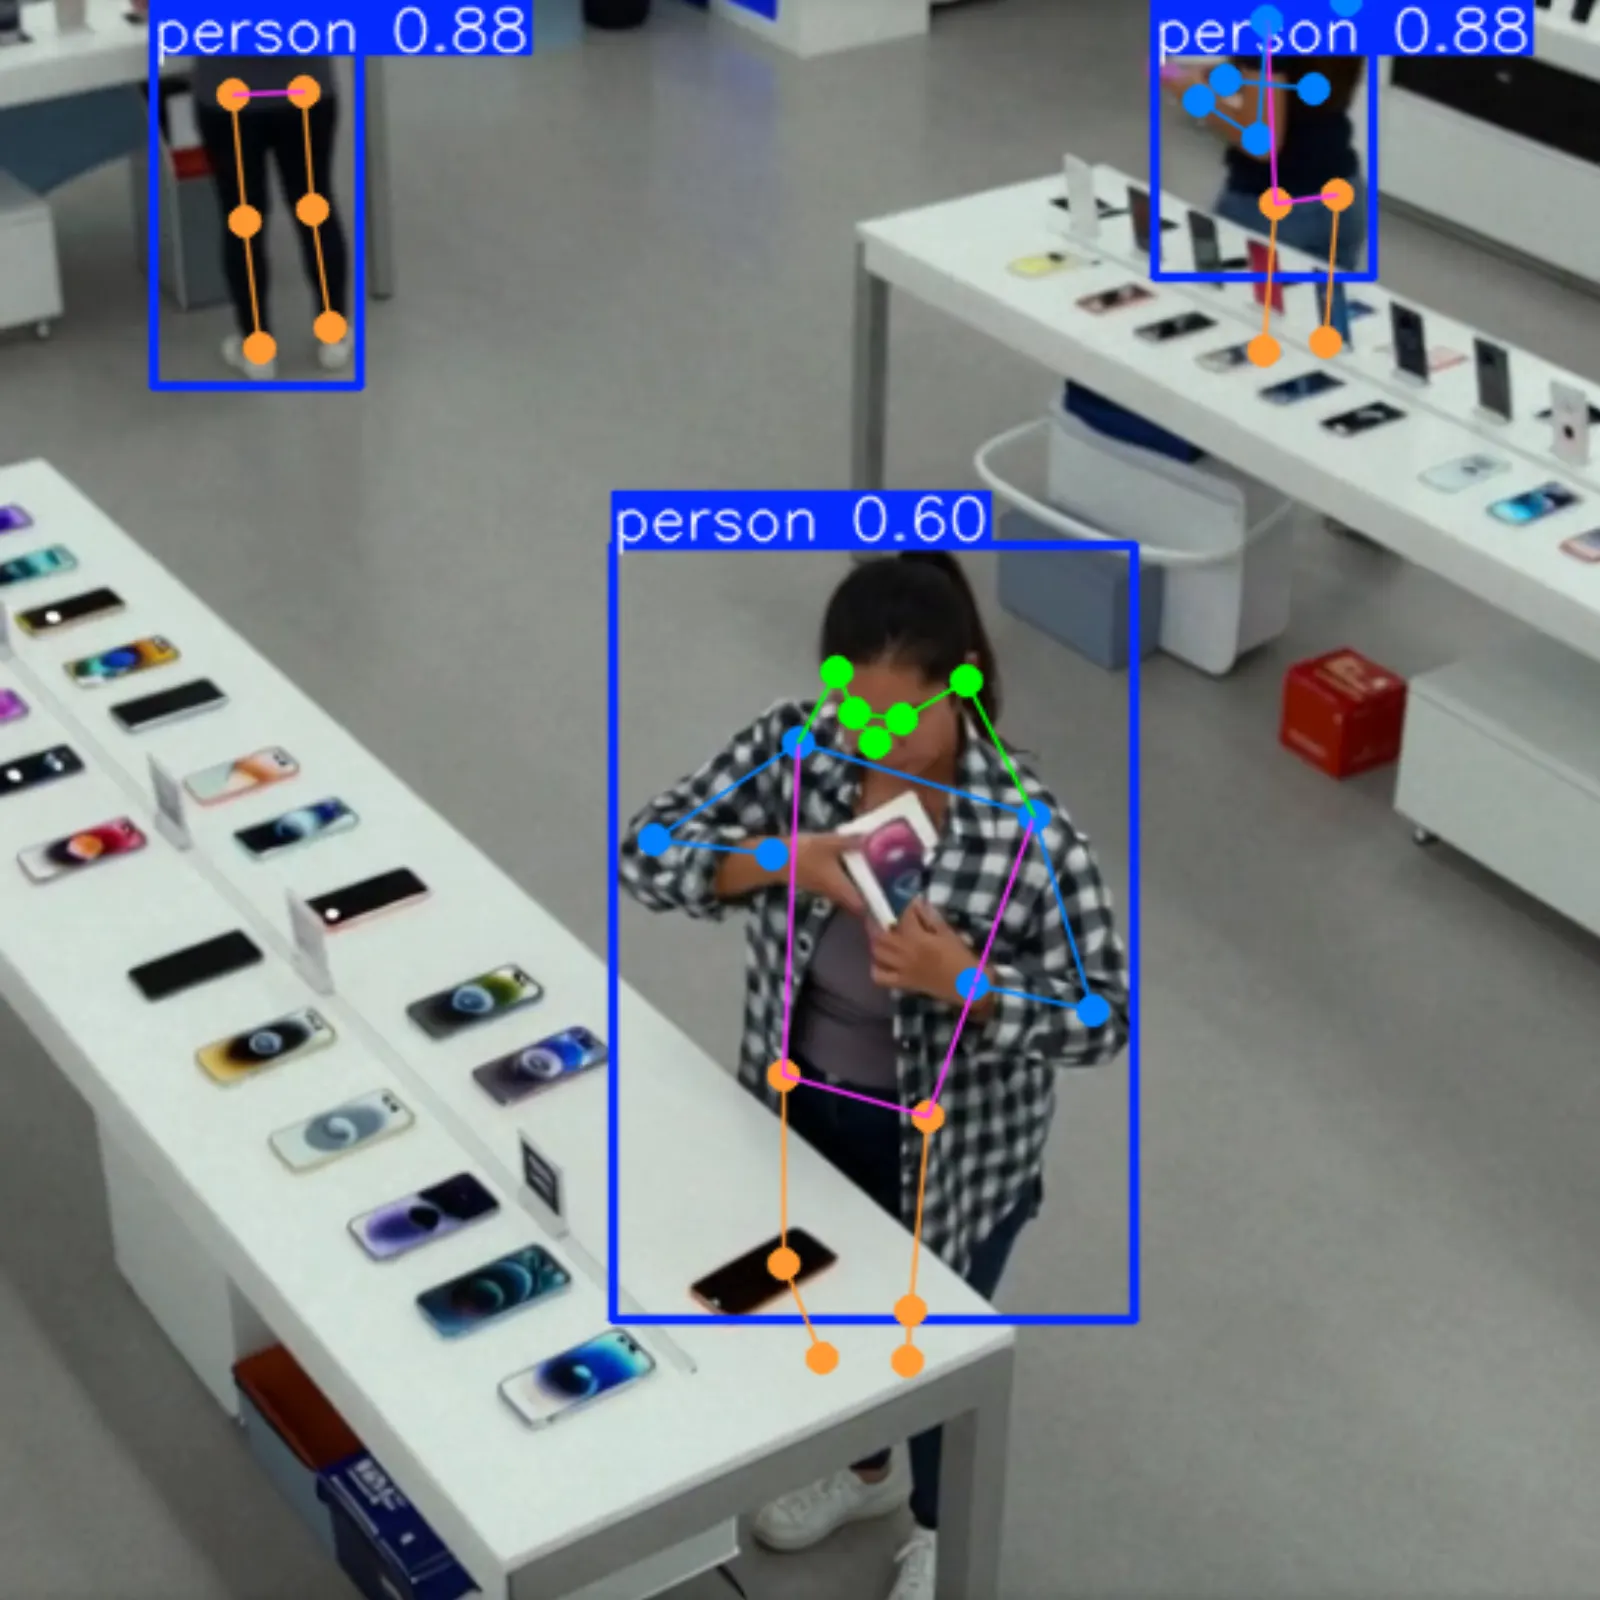
- Rare events in volume. UCF-Crime, one of the largest incident sets, has 50 shoplifting and 50 fighting videos. A deployed model needs many more examples, from varied scenes.
- Your camera angle. Most clips are handheld, film or lab footage. A camera mounted high on a wall or ceiling changes how a fall, a knife or a concealed item looks.
- Look-alikes. None of the sets deliberately labels the things that trigger false alarms: someone sitting on the floor, an umbrella, a hug.
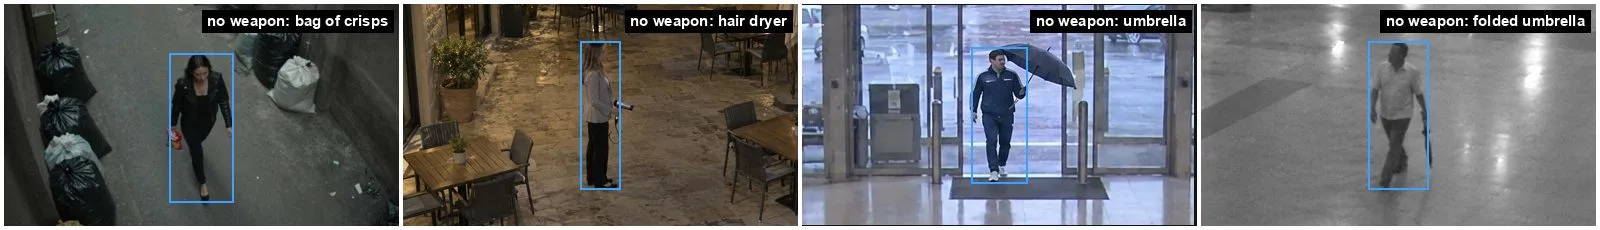
That is the gap our synthetic CCTV datasets fill. Each is seen from real CCTV positions, labelled, and includes look-alike negatives:
Falls from a ceiling camera
Fights vs. hugs and horseplay
Shoplifting and concealment
Weapons and look-alikes
ATM robbery roles
Smoke and fire starting
The catalogue datasets are labelled images (1,000 per licence); the shoplifting dataset includes video. Video clips with per-frame boxes, tracking IDs and event start/end times are made to order on your own camera views; see custom data.
FAQ
What is the largest public video dataset for action recognition?
Of the sets in this table, Kinetics-700 is the largest labelled action set at about 650,000 ten-second YouTube clips in 700 classes. MEVA has more raw footage (over 9,300 hours) but only about 22 hours of public annotations.
Which video datasets can I use commercially?
Few. MEVA is CC BY 4.0 and AVA's annotations are CC BY 4.0 (the films are not). NTU RGB+D and UCF-Crime are research-only, UBnormal is non-commercial, RWF-2000 needs the lab's approval, and the YouTube-based sets leave the video rights with the uploaders.
Which public video dataset is closest to real CCTV?
MEVA (fixed RGB and thermal cameras at one venue, CC BY 4.0), UCF-Crime (real CCTV incidents, research-only) and RWF-2000 (surveillance fights) are closest. ShanghaiTech and CUHK Avenue are fixed cameras too, but on a single campus.
Do I need video, or are images enough?
Most CCTV alerting runs a detector per frame plus simple rules over time, so labelled images from the right camera angle carry most of the value. Temporal models (3D CNNs, video transformers, skeleton sequences) need clips with start and end times.
Does Simuletic sell video datasets?
The catalogue is mostly labelled image datasets; the shoplifting dataset includes video sequences and a few sets add evaluation clips. Video with per-frame boxes, tracking IDs and event start/end times is made to order on your own camera views.
Need a video dataset that doesn't exist yet?
Send us the behaviour, a few stills of your empty camera views and the label format. We make synthetic clips with per-frame labels, quoted per project.